Charts + visual tables
From grouped bars and multi-series lines to heatmaps and diagrams. Tables distinguish simple, row-spanning, column-spanning and mixed-spanning structures.
Explore visual categories ↗MInfoVisQA: A Multilingual Benchmark for Information-Rich Visual Question Answering
128 seed questions across 24 languages. How well do multimodal models understand the same charts and tables when the visual language changes?
Parallel questions and visuals preserve the underlying quantities and structure, making language a deliberate part of the evaluation.
From grouped bars and multi-series lines to heatmaps and diagrams. Tables distinguish simple, row-spanning, column-spanning and mixed-spanning structures.
Explore visual categories ↗Evaluate each language with its own visual, question and answer. Then ask in Chinese or English about visuals in each of the other 23 languages.
Understand the protocol ↓Source-linked questions, labels and QA translated with Google Translate API, reproducible renderers and image hashes. Charts and tables enter the model as images, preserving the visual task.
See the pipeline ↗One shared evaluation framework.
XQA-ZH / EN: 23 cross-language settings each. LQA mean: mean of the 24 displayed same-language scores. AVG: macro-average of all 70 configurations.
Results JSON ↗All 26 models and 702 score cells are synchronized with the current manuscript main table. The table uses exact matching followed by text-only GPT-6 Astra judging for non-matches. Scores are author-reported; this website does not independently rerun the evaluations. View the frozen source table.
Reported scores and the original AVG are preserved at one decimal. AVG weights all 70 configurations; it is not the mean of the 26 visible XQA/LQA columns. LQA mean is computed from the 24 displayed language scores. Model grouping follows the paper; open weights does not imply these runs were self-hosted. Official model links are shown where previously documented.
Ranks use the reported overall AVG; tied scores share a rank. Language variants share the same seed question, so 8,960 configurations do not represent 8,960 independent questions.
Explore actual localized examples from the released dataset. Switch the visual language and question setting to see what the model receives.
Select an image to inspect its question and reference answer below.
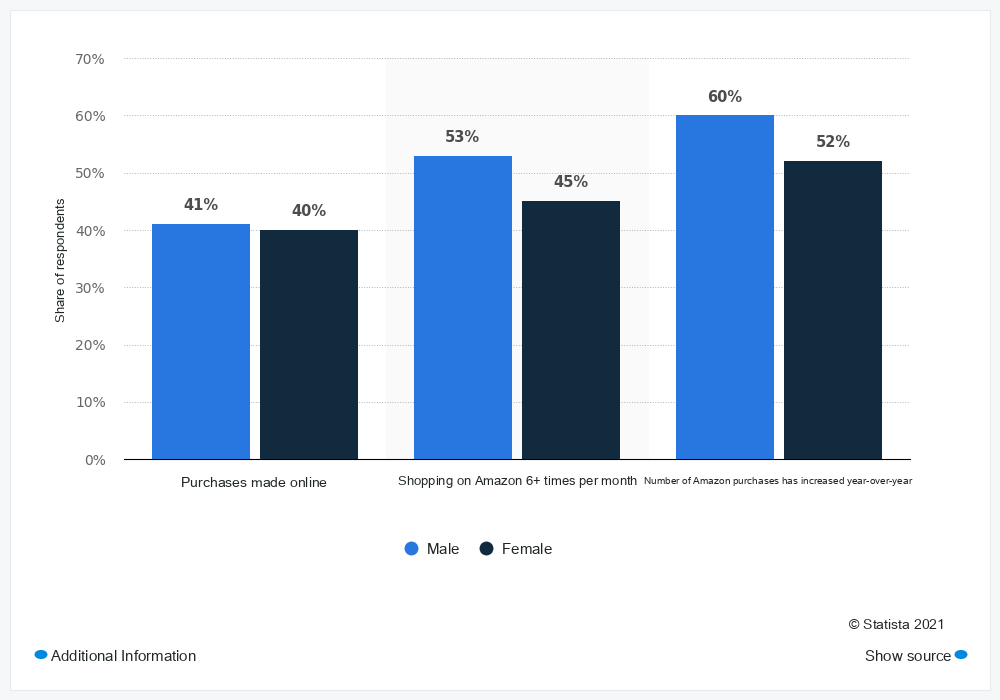 Released image · click to view at full resolution ↗
Examples are copied without modification from the current release. Source attribution and original identifiers are retained; source-specific dataset terms apply.
For each base QA, the visual language changes while the task stays linked to the same source. Question and answer always share a language.
Visual language →
Each input contains a localized image and question. Original external prose, when required, is translated into the question language using Google Translate API. Tables are never replaced by text transcriptions.
Exact answer matches are accepted. Other completed answers go to a text-only equivalence judge. The judge receives no image; unconfirmed equivalence counts as incorrect.
Each XQA column averages 23 visual languages. Each LQA column evaluates a single aligned language. AVG gives equal weight to all 70 configurations.
128 base questions × 70 configurations = 8,960 QA instances. Language variants share their base identity and are not independent source observations. Automated construction and review do not constitute complete human verification. See the dataset card for scope, quality flags and limitations.
Download the frozen benchmark, evaluate your model and share scores with the configuration needed to reproduce them.
Include the exact model identifier, dataset revision, inference settings, judge configuration, coverage and failure counts, plus all 70 configuration scores.
Submit results on GitHub Leaderboard maintenance guide ↗If you use MInfoVisQA in your research, please cite our preprint.
@article{jiang2026minfovisqamultilingualbenchmarkinformationrich,
  title={MInfoVisQA: A Multilingual Benchmark for Information-Rich Visual Question Answering},
  author={Jiang, Changjiang and Zhou, Jiang and Yuan, Xinbin and Zhang, Fan and Feng, Tao and Xie, Zhuohan},
  journal={arXiv preprint arXiv:2611.21644},
  year={2026}
}